







AnythingLLM

Deploy AnythingLLM on a VPS in One Click

AI & LLM tools

Self-hosted AI workspace for chatting with your documents, running RAG pipelines, and building no-code AI agents.

  • Ready in ~5 min
  • Free installation
  • We handle the setup
At a glance
Version
Latest (1.18)
Operating system
Ubuntu Server 24.04 LTS
Minimum RAM
2 GB
License
MIT
Addressing
IPv4, IPv6
GitHub
67,000
Deployment~5 min
Open source & self-hosted
VPS plans

Choose a VPS plan for AnythingLLM

Blazing-fast NVMe drives and powerful processors. Take a ready-made plan or build the configuration yourself.
Minex
Perfect for personal projects and small websites.
€3.20/mo
Save €0.80 per month

  • 1 vCPU core
  • 1 GB DDR5 RAM
  • 20 GB NVMe SSD
  • Full root access
  • 1 dedicated IPv4
  • 1 TB traffic
Basex
A great balance of power and affordable price.
€4.80/mo
Save €1.20 per month

  • 2 vCPU cores
  • 2 GB DDR5 RAM
  • 40 GB NVMe SSD
  • Full root access
  • 1 dedicated IPv4
  • 2 TB traffic
Most popular
Corex
For growing applications and businesses.
€7.20/mo
Save €1.80 per month

  • 4 vCPU cores
  • 4 GB DDR5 RAM
  • 50 GB NVMe SSD
  • Full root access
  • 1 dedicated IPv4
  • Unlimited traffic
Midex
Resources for high-load projects.
€9.60/mo
Save €2.40 per month

  • 4 vCPU cores
  • 6 GB DDR5 RAM
  • 60 GB NVMe SSD
  • Full root access
  • 1 dedicated IPv4
  • Unlimited traffic
Proex
Maximum power and scalability.
€12.00/mo
Save €3.00 per month

  • 6 vCPU cores
  • 8 GB DDR5 RAM
  • 70 GB NVMe SSD
  • Full root access
  • 1 dedicated IPv4
  • Unlimited traffic
Scalex
Resources for scaling.
€16.00/mo
Save €4.00 per month

  • 6 vCPU cores
  • 10 GB DDR5 RAM
  • 150 GB NVMe SSD
  • Full root access
  • 1 dedicated IPv4
  • Unlimited traffic
Maxex
A large reserve of power.
€44.00/mo
Save €11.00 per month

  • 8 vCPU cores
  • 16 GB DDR5 RAM
  • 200 GB NVMe SSD
  • Full root access
  • 1 dedicated IPv4
  • Unlimited traffic
Apex
The top configuration.
€79.99/mo
Save €20.00 per month

  • 16 vCPU cores
  • 32 GB DDR5 RAM
  • 400 GB NVMe SSD
  • Full root access
  • 1 dedicated IPv4
  • Unlimited traffic

What you can do with AnythingLLM

AnythingLLM is an open-source AI workspace for chatting with your own documents, connecting to dozens of LLM providers, and building no-code AI agents in one self-hosted app. A single AnythingLLM installation replaces the usual stack of separate vector databases, embedding services, and chat frontends that teams otherwise wire together by hand. Built by Mintplex Labs, it's aimed at developers, IT teams, and businesses running retrieval-augmented generation (RAG) without locking into one vendor.

Unlike most RAG tools tied to a single model or a proprietary vector store, AnythingLLM works with more than 40 LLM providers — OpenAI, Anthropic, Ollama, LM Studio among them — plus several vector databases, so any component can be swapped without rebuilding the setup. Document embeddings, chat history, and API keys never have to leave a server you control; running AnythingLLM self hosted is the only way to keep sensitive internal knowledge off a third party's infrastructure entirely.

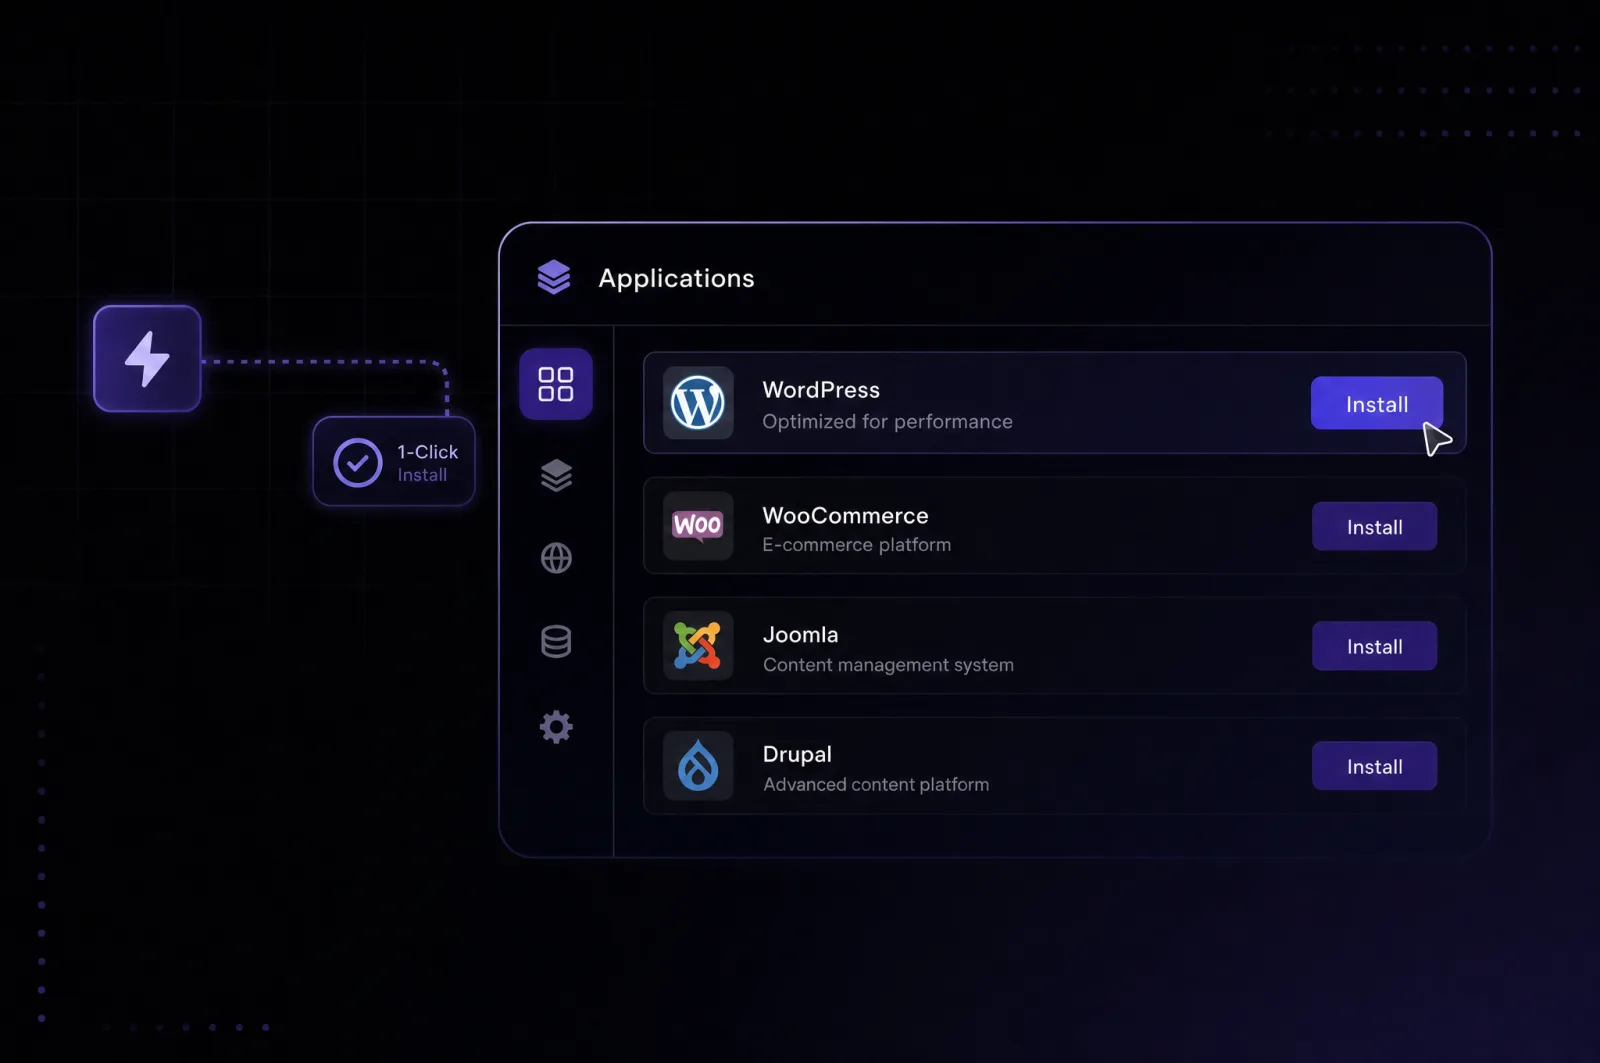
The applications screen of the control panel with one-click install

AnythingLLM features

A server surrounded by app icons — applications running on a VPS

An AnythingLLM VPS Docker deployment ships with the full RAG and agent toolkit already wired together — nothing extra to install separately.

01

Multi-user workspaces

Isolate documents, permissions, and chat history per team or project.

02

Agent Flows (no-code builder)

Chain LLM calls, web requests, and file actions into automations without writing code.

03

MCP compatibility

Connect external tools and data sources through Model Context Protocol servers.

04

Embeddable chat widget

Add a branded, document-aware chat window to any website.

05

Multi-provider LLM routing

Switch between OpenAI, Anthropic, Ollama, LM Studio, and dozens of other providers per workspace.

06

Built-in vector database (LanceDB)

Index documents with zero external setup, or point instead to Chroma, Pinecone, or Qdrant.

07

Developer API

Automate workspace creation, document uploads, and chat through REST endpoints.

08

Password protection and user invites

Control who can view or edit each workspace, available only in the Docker build.

Requirements

Which server to run it on

Minimum requirements for AnythingLLM and the configuration worth starting with.
Minimum
  • CPU2 vCPU
  • Minimum RAM2 GB
  • Disk20 GB
Recommended
VPS Corex
  • CPU4 vCPU
  • Minimum RAM4 GB
  • Disk50 GB

Installation is free — you only pay for the server

Getting started

How to deploy AnythingLLM

Three steps and the app is running on your server.
Step 1
Choose a server

Pick a plan with headroom above the minimum requirements listed above — extra RAM matters most if you plan to run a local embedding model or Ollama alongside AnythingLLM.

Step 2
Pick the app

Select AnythingLLM in the Leneex marketplace and the AnythingLLM one click install process pulls the official Docker image and configures persistent storage automatically.

Step 3
Get your credentials

Open your server's address in the browser and complete the setup wizard yourself — AnythingLLM has no default admin password to look up, you create the account on first visit.

Why us

Why Host AnythingLLM on Leneex

Speed, protection and support you can rely on — on every plan, with no hidden limits.
Deployment speed
Wiring a RAG stack by hand normally means standing up a vector database, an embedding service, and a chat frontend separately. On Leneex the whole AnythingLLM container — LanceDB, document collector, and web UI included — is running within minutes.
Free installation
Self-hosting removes the per-seat and per-document caps of a managed RAG service; you pay only for the server, not for team size or how many documents you index.
DDoS protection
Once you embed AnythingLLM's chat widget on a public website, that endpoint is public-facing traffic like any customer-facing app, so protection against flood attacks matters as much as it would for a storefront.
Control and support
Root access lets you attach a local Ollama instance, mount custom vector databases, or edit the .env file directly — none of which a managed cloud tier of AnythingLLM allows.
99.9% uptime with SLA compensation
If your team or customers rely on AnythingLLM as a live support or internal-knowledge chat, downtime blocks that channel entirely, so the SLA-backed guarantee carries real weight.
Flexible payment
Companies expensing an internal AI tool can pay by invoice instead of a recurring per-seat SaaS subscription tied to a credit card.
What to choose

AnythingLLM: Self-Hosted vs Cloud — Which to Choose

AnythingLLM offers an official cloud service, AnythingLLM Cloud, with Basic plans priced at $50 per month, Pro at $99 per month, and Enterprise available upon request. The comparison below is made against it.
AnythingLLM Cloud
Self-hosted on LeneexRecommended
Resources and limitsBasic tier caps at under 100 documents and 3 team membersFull server resources; no cap on documents or team members
Control and accessManaged AWS instance, no root access, updates handled by MintplexRoot access, direct .env editing, choice of Docker image/version
Feature limitsCustom domain reserved for the Enterprise tier; Basic gets only a subdomainCustom domain, MCP servers, and local LLM connections available on any plan
ScalingScaling means upgrading from Basic to Pro to EnterpriseResize the VPS at any time, independent of user count
Cost$50–$99/month recurring, tied to seats and document countFixed server price regardless of team size or document volume
Who it fitsTeams wanting zero infrastructure management and are fine with seat-based pricingTeams needing local LLM connectivity, custom domains, or more than 3 users/100 docs

Self-hosted AnythingLLM on a VPS pays off once a team exceeds the Basic tier's 3-user or 100-document caps, since the VPS cost stays flat while the Cloud subscription would require an upgrade. It also makes sense for anyone who wants to connect a local LLM through Ollama, since AnythingLLM Cloud runs on Mintplex's managed AWS instances without that same-box access.

Frequently Asked Questions about AnythingLLM on VPS

What people ask most about AnythingLLM and our servers.

  • There's no built-in migration tool between AnythingLLM Cloud and a self-hosted deployment; documents and their embeddings live in the storage folder mounted to your VPS, so moving between servers means copying that folder manually.

  • Nothing changes — AnythingLLM's documents, vector embeddings, and chat history live in a persistent storage volume, and resizing CPU or RAM doesn't touch that volume.

  • Check your deployment settings or contact support before exposing the instance publicly.

  • The official AnythingLLM Docker baseline of 2 GB RAM and a 2-core CPU comfortably supports a small internal team chatting through a remote LLM provider like OpenAI or Anthropic; running a local model on the same server needs considerably more RAM.

  • You are — Mintplex Labs publishes new Docker images on a near-daily basis for the latest tag and with each versioned release, so applying updates means pulling a new image and restarting the container yourself.

What's already configured

The Docker container bundles the AnythingLLM server, the document collector, the web frontend, and LanceDB as the default embedded vector database — there's no separate database service to install or connect. Documents, vector embeddings, chat history, and your .env configuration all persist in a storage volume mounted to the container, so restarts or image updates don't wipe your data. Anonymous usage telemetry (PostHog-based) is enabled by default; it can be disabled by setting DISABLE_TELEMETRY="true" in the .env file if you'd rather not send it.

First login and admin setup

There's no pre-generated admin password. On first visit to your instance, AnythingLLM walks you through a setup wizard where you create the admin account, choose between single-user and multi-user mode, and pick your first vector database and LLM provider. The exact URL, port, and whether SSL is pre-configured on Leneex depend on how this app is wired into the panel.

Connecting a model before you can chat

The Docker image doesn't ship with a bundled LLM — after finishing the setup wizard, the workspace won't answer anything until you add a provider (an OpenAI or Anthropic API key, or a local Ollama endpoint) in the settings. The same applies to the embedding model used for indexing documents; the built-in option works out of the box, but it can be swapped for an external provider from the same settings screen.

Deploy AnythingLLM in about 5 minutes

Choose a server — we do the rest: install, configure and send you the credentials.